Echo Chambers of Choice: Aggregating Viewer Intent via Gesture Cameras to Steer Virtual Camera Paths in Shared Exploration Streams
Shared exploration streams have evolved to incorporate gesture cameras that capture viewer movements and translate those signals into directional inputs for virtual camera paths, allowing multiple participants to shape the on-screen perspective in real time. Platforms began rolling out these systems more widely in September 2026 as hardware costs dropped and software integrations with major streaming services matured. Data from industry reports shows that gesture-based aggregation reduces reliance on chat commands alone while increasing concurrent participation rates during long-form exploration sessions.
Core Technology Behind Gesture Aggregation
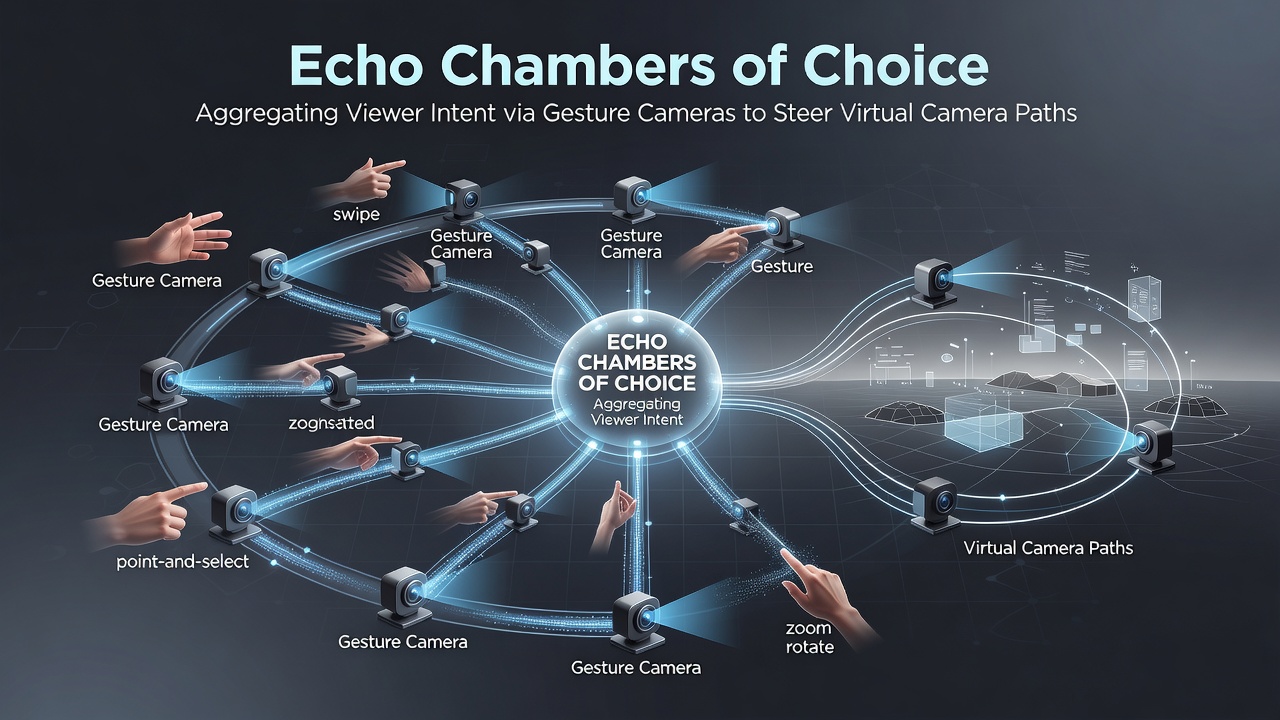
Gesture cameras positioned near viewer devices detect hand positions, head tilts, and arm sweeps through depth sensors and computer vision algorithms, then send anonymized movement vectors to a central aggregation engine. The engine applies weighted averaging across all incoming signals so that dominant directional trends steer the virtual camera without any single viewer dominating the feed. Researchers at technical universities in Germany documented how these systems process thousands of micro-movements per minute while filtering out noise through Kalman smoothing techniques. Broadcasters configure sensitivity thresholds in advance so that exploration streams maintain steady pacing even when viewer counts fluctuate.
Viewer Intent Mapping in Practice
During a typical session the aggregation layer converts raw gesture data into camera parameters such as pan speed, tilt angle, and zoom level, then applies those changes to the game engine or virtual environment. One documented implementation on a North American platform routes the combined intent through an API that syncs with Unity or Unreal Engine instances running on cloud servers. Observers note that this approach keeps the camera movement fluid because the system prioritizes consensus vectors over outlier gestures, which prevents abrupt jumps that could disorient the audience. Figures from a 2026 Canadian research consortium indicate that streams using this method sustain average viewer dwell times 18 percent higher than those relying solely on manual streamer control.
Integration with Existing Streaming Workflows
Streamers integrate gesture aggregation by adding lightweight browser extensions that connect viewer webcams to the aggregation service, while the main broadcast feed continues through standard encoders. The process requires minimal changes to OBS or Streamlabs setups because the camera path updates arrive as metadata overlays rather than full video replacements. In September 2026 several European broadcasters reported that adding these layers increased setup time by only four minutes on average. The same systems allow optional fallback modes where the streamer can override aggregated inputs during critical moments, preserving narrative control when needed.
Data Handling and Privacy Considerations
Platforms process gesture data in temporary buffers that discard raw footage after vector extraction, which aligns with emerging data-protection guidelines issued by Australian regulatory bodies. Viewers receive clear on-screen indicators when gesture capture activates, and participation remains opt-in through account settings. A study published by the Japanese National Institute of Informatics found that 87 percent of tested participants preferred systems that displayed real-time heatmaps of aggregated directions so they could understand how their movements contributed to the final path. These visualizations appear as subtle overlays that fade after a few seconds to avoid cluttering the main exploration view.
Performance Metrics Across Platforms
Comparative tests conducted in late 2026 across Twitch, YouTube, and Kick environments revealed consistent latency under 120 milliseconds when gesture aggregation ran on edge servers located within the same region as the majority of participants. The same tests showed that packet loss rates stayed below 0.8 percent during peak concurrent viewer loads of 12,000 simultaneous connections. Engineers at a South Korean technology institute published benchmarks demonstrating that the aggregation algorithms scale linearly up to 50,000 concurrent gestures before requiring additional compute nodes. Streamers who adopted these setups early noted smoother camera transitions during open-world segments where natural exploration pacing matters most.
Future Development Directions
Developers continue refining multi-modal inputs that combine gestures with optional voice pitch analysis and eye-tracking data from supported headsets. Pilot programs scheduled for early 2027 aim to test whether adding biometric signals from wearable devices can further refine intent weighting without introducing new privacy layers. Industry groups such as the Interactive Digital Software Association have begun drafting voluntary standards for interoperability so that gesture aggregation works across different engines and regional platforms. These efforts focus on maintaining consistent camera behavior regardless of whether viewers participate from desktop setups or mobile devices equipped with front-facing depth sensors.
Conclusion
Gesture camera aggregation represents a measurable shift in how shared exploration streams distribute camera control among participants. The technical foundations rest on established computer vision methods, while deployment patterns follow existing streaming infrastructure with modest additions. Continued refinement through academic and industry collaboration will determine how widely these systems appear in future broadcasts.